New in 0.4.0Images, video frames, guardrails and the Decision Bench → System 0 · your model's shadow · text, images, video

Your AI's repeat decisions, in microseconds.

shad0w is your model's shadow. It watches your LLM or vision model, learns to answer like it, and takes the repeat decisions (intents and routing, moderation and prompt attacks, images and video frames) in microseconds. Your model only gets what shad0w isn't sure about.

2.4 µs per answer≤ 5% differs from your LLM, 90% confidence1 line of code, or none
pip install "shad0wllm[compile]"
livereal messages · 77 intents · in this tab
incoming message

Loading a real 77-intent model…

shad0wyour LLM's shadow
sure: shad0w answers
–
not sure: your LLM
idle
–
–answered by shad0w, so far
–per answer, timed in this tab
–of LLM waiting skipped
proof

Measured, not promised.

A real hosted LLM, the official OpenAI client, public datasets. Every number below is rebuilt from a result file.

time per answer
2.4 µs
vs 1416 ms for one call to your LLM

shad0w runs inside your app. No network hop, no GPU.

8 intents
94.3%

of messages answered by shad0w instead of your LLM. On those, it agreed with your LLM 97.2% of the time.

3 public datasets
61–86%

of messages answered by shad0w instead of your LLM. On those, it gave a different answer than your LLM 3.0–6.0% of the time.

teacher: a hosted LLM through the official OpenAI client · agreement re-checked by asking the LLM directly

All benchmarks →
see it at work · 126 seconds

What it is, and five jobs it does.

How it learns and the test it passes, the work real teams give it, and how you start. Every message, photo, decision and number on screen is real.

shad0w at work: the wordmark, and the line: it learns your LLM's repeat answers and gives them back in microseconds
multimodal · new in 0.4

One reflex, every input.

The same loop (a small table that learns your model's answers, and a certificate that says when to trust it) runs on text, pixels and video frames. Each card is something you can try.

try it

Type anything. It answers first.

A real shad0w that learned 77 banking intents, running in this tab. See what it picks, how sure it is, and whether it answers or asks your LLM.

Loading the model…

77 intents · learned from an open model's answers · certified at α = 5% · open the playground →

how it works

Watch. Learn. Prove. Serve.

shad0w is your LLM's shadow. It watches every answer, learns to answer the same way, and proves where it can. Then most repeat traffic goes to shad0w, and your LLM only gets what shad0w isn't sure of.

01

Watch

Your LLM keeps answering. Its shadow writes down every question and answer.

02

Learn

About 1,000 answers become a tiny model. No labels, no GPU.

03

Prove

On answers it never saw, it finds the confidence line above which it agrees with your LLM.

04

Serve

Above the line, shad0w answers. Below it, your LLM does, and shad0w learns.

In plain words: certified means shad0w was tested on answers it never trained on, and only answers above the confidence where it differs from your LLM on at most α of its answers, checked with 90% confidence. α is the most disagreement you allow: the default 5% means at most 1 in 20. How the guarantee works →

it tunes itself

Fine-tuning you don't have to do.

No labels, no GPU, no hyperparameters. shad0w learns from your LLM's own answers, keeps learning from every answer it gives, and earns each step into production.

It learns from your LLMEvery answer your LLM gives is logged. That log is the training data: no labelling project, no GPU. Training starts once 1,000 answers are in (min_rows).
It retrains on its own, if you let itTurn on auto_train=2000 (or shad0w proxy --auto-train 2000) and it retrains in the background every 2,000 new answers. It is off by default; shad0w train on a schedule works too.
A new version must earn its placeThe quality gate keeps the current version unless the new one is nearly as good. The certificate is recomputed every time, and the confidence line is picked for you: you only choose α, if you want.
It checks itself in productionSpot checks re-ask your LLM in the background, and the dashboard warns when live agreement drifts past α. When traffic changes, the drift guard sends messages back to your LLM. A new option? shad0w steps back until it has learned it.

Training & retraining →Tuning →

Then prove it on your own traffic, before it answers anything.

01

Shadow

Your LLM still answers everything. The dashboard shows what shad0w would have said, and how often it agreed.

02

Canary

shad0w answers a slice of traffic. Spot checks re-ask your LLM in the background.

03

Serve

shad0w answers what it is certified on. It steps back on its own when your options change or traffic drifts.

the reflex

Microseconds vs seconds.

The shadow answers before the LLM writes its first token.

your LLM · a hosted modelwaiting
"my card got stolen at the airport"
–
typical time per call, measured: 1416 ms
shad0w · your LLM's shadowready
"my card got stolen at the airport"
 
–
typical time per answer, measured in Python: 2.4 µs
real timings, replayed at real speed

Every runtime, one scale

time per decision, log scale. shad0w in orange.

at game speed

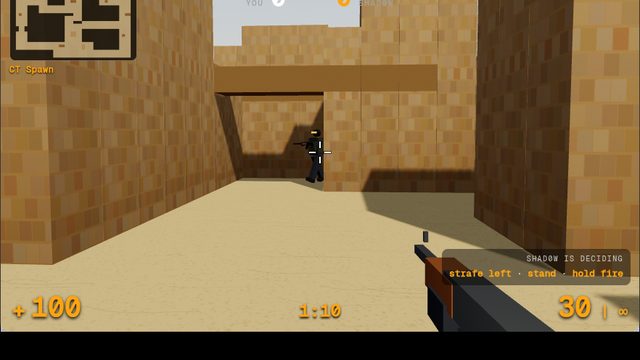
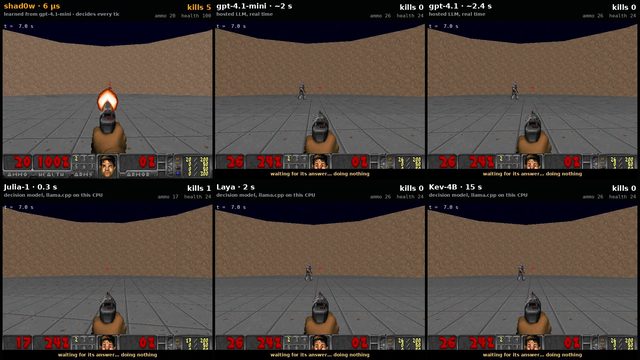
Fast enough to play.

A game gives every decision a few milliseconds. We taught shad0w four games from an LLM's answers, then put it where speed decides who wins.

Everything in the Playground →

integrate

One line, or zero.

Wrap your call, or point base_url at the proxy.

pythonsupport_router.py
import shad0w

intent = shad0w.decision("intent", llm="openai/gpt-6-luna",
    options=["refund", "lost_card", "balance", "other"])

intent("my card was stolen").answer   # your LLM answers; shad0w logs it
intent.train()                        # after ~1,000 answers
intent("my card was stolen")          # Decision(answer='lost_card', source='table')

Async: await intent.adecide(text). Bring your own LLM function: shad0w.Shadow("bundle/", teacher=my_fn).

javascriptroute.mjs
import { decision } from "shad0wllm";

const intent = await decision("intent", {
  options: ["refund", "lost_card", "balance", "other"],
  llm: "openai/gpt-6-luna", bundle: "shad0w/intent/bundle" });

const d = await intent.decide("my card was stolen");
// { answer: "lost_card", source: "table", certified: true }

Zero dependencies. Node, browsers, Workers, Deno, Bun. Same answers as Python on the same trained shad0w.

shell + pythonno code change
# 1. start the proxy (dashboard at http://localhost:8010)
#    shad0w proxy --upstream https://api.openai.com/v1 --auto-train 1000

# 2. move base_url. Nothing else changes.
client = OpenAI(base_url="http://localhost:8010/v1")
client.decisions.create(model="gpt-6-luna", input="my card was stolen", questions=[...])

# answers shad0w is sure of come back instantly, same JSON shape;
# the rest go upstream and are logged so shad0w keeps learning

Works for the Decisions API, System One servers and chat completions (mark a call with the X-Shad0w-Question header).

fit

Built for lists, not essays.

If your LLM picks from a fixed list, shad0w can learn it. If it writes, it can't.

fits

Support intent routing→ lost_card
Ticket triage: team, priority→ team: mobile
Moderation pre-filter→ spam: yes
Agent tool routing→ tool: search
Tagging and topics at ingest→ topic: business
In a browser or at the edgeno network

doesn't fit

Sarcasm, humour, subtle tone→ LLM
Generated text: replies, summaries→ LLM
Questions needing world knowledge→ LLM
One-off, low-volume calls→ LLM
Is it for me? Six questions, thirty seconds.
compare

Same certifier, every method.

Held to one test on the same answers: caches, routers and a fine-tuned head on your LLM's answers; open decision models on six public tasks, all on a CPU.

methodanswered without the LLM @ α = 5%disagreement with the LLM on thoseaccuracy vs gold (cascade)p50 per decisioncost per 1k decisionsneedsguarantee
shad0w61%3.0%76.5%4.0 µs$0.204your LLM's logged answerscertified ≤ α vs your LLM
semantic cache (bge-small, nearest logged answer)0%—76.3%7.5 ms$0.520embedding model + logged answerssame certifier applied
embedding kNN router (bge-small, k=10)69%2.9%76.9%7.6 ms$0.161embedding model + logged answerssame certifier applied
small fine-tuned head (LR on bge-small)75%3.4%77.1%7.2 ms$0.129embedding model + logged answerssame certifier applied
exact-match cache0%—76.3%1.2 µs$0.520logged answersexact repeats only
keep calling the LLM0%0.0%76.3%—$0.520API or GPUit is the reference
Kev-0.8B decision model (local)100% (it replaces your LLM)23% vs a hosted LLM80.0%271 ms$0 (your hardware)a GPU/MLX machine, ~1-3 GBcalibrated probabilities, no bound
Julia-1 decision model (local)100% (it replaces your LLM)41% vs a hosted LLM61.6%11.9 ms$0 (your hardware)llama.cpp, a laptopcalibrated probabilities, no bound
Laya 421M decision model (local)100% (it replaces your LLM)58% vs a hosted LLM38.0%91.6 ms$0 (your hardware)a GPU or fast CPU, 0.8 GBcalibrated probabilities, no bound
hosted decision model (OpenAI Decisions API, gpt-6-luna)100% (it replaces your LLM)not measured (no API key)not measured~150 ms claimed$0.030 per 1kAPI keynone (probabilities only)
hosted decision model (TypeSafe Jev 1.13)100% (it replaces your LLM)not measured (no credits)not measured70–500 ms claimed$0.0126 per 1kAPI keynone (probabilities only)

Decision models (Kev, Laya, Julia, the Decisions API) replace your LLM instead of shadowing it. An embedding model answers a bit more, but takes milliseconds and over a hundred megabytes. shad0w answers in microseconds from a 1.5 MB file. Full comparison →

taskshad0w: accuracy · timebest open decision model, zero-shotmore accurate
BANKING77 · 77 intents94.0% · 6.0 µsKev-0.8B: 83.3% · 2.6 sshad0w
CLINC150 · 150 intents84.6% · 6.5 µsDecider-0.8B: 83.3% · 5.6 sshad0w
AG News · topics91.2% · 10.1 µsLaya: 93.8% · 124 msLaya
SST-2 · sentiment83.2% · 3.0 µsLaya: 91.6% · 49 msLaya
SMS spam97.8% · 1.9 µsDecider-0.8B: 95.3% · 3.6 sshad0w
Prompt injection98.8% · 2.4 µsGLiNER2.5-Decide: 94.6% · 113 msshad0w

Julia-1, Laya, Kev-0.8B, Decider-0.8B and GLiNER2.5-Decide answer zero-shot on 5 CPU threads over localhost; shad0w learns each task's training split and runs on one thread. They'd be faster on a GPU, and better if fine-tuned. Every task, chart and caveat →

honest limits

Where it loses.

We publish these next to the wins.

2 of 6tasks
Less accurate than the best decision model on news and sentimentOn the Decision Bench, Laya (zero-shot) beat shad0w on AG News and SST-2. shad0w was faster everywhere, and in front of Laya it served most messages and lifted the combined accuracy. See the bench.
0%cold start
Many options need data firstWith 77 intents, shad0w answers nothing until a few thousand LLM answers are logged. Then it takes 40% of messages at 5,000 and 60% at 10,000.
51.3%77 intents
More options, smaller shareWith 77 intents, shad0w answered this share of messages end to end, versus 94.3% with 8 intents. The rest went to your LLM, as it should.
Honest numbers, in full →

It learns as you log

share of messages shad0w answers (at α = 5%), by how many LLM answers it has seen

faq

Questions people ask

Is this just a cache?

No. A cache only answers texts it has seen before. shad0w answers new wordings of a question it has learned, and its guarantee covers new messages that look like your traffic. Exact repeats are free on top.

What does "certified" mean?

Before it answers anything, shad0w is tested on answers it never trained on and picks a confidence line. Above it, shad0w differs from your LLM on at most α of what it answers, checked with 90% confidence. α is the most disagreement you allow: the default 5% means at most 1 in 20 answers. In our runs, shad0w actually differed 3.0–6.0% of the time: a 90% promise can miss, so live spot checks keep watching.

How many examples does it need?

About 1,000 logged answers per question to start. More options need more: with 77 intents it answered 60% at 10,000 answers. The share keeps growing as your LLM keeps answering.

What if my LLM is wrong?

Then shad0w is wrong in the same way. The guarantee is agreement with your LLM, not with the truth. For a bound against the truth, certify on a few hundred human-labelled examples instead.

What does it cost?

Nothing. It is Apache-2.0 open source. The Python runtime needs only numpy; the JavaScript and C runtimes need nothing. Your data and logs stay on your machine.

Give your LLM
a shad0w.

Open source, Apache-2.0. CPU, browser, edge.

pip install "shad0wllm[compile]"